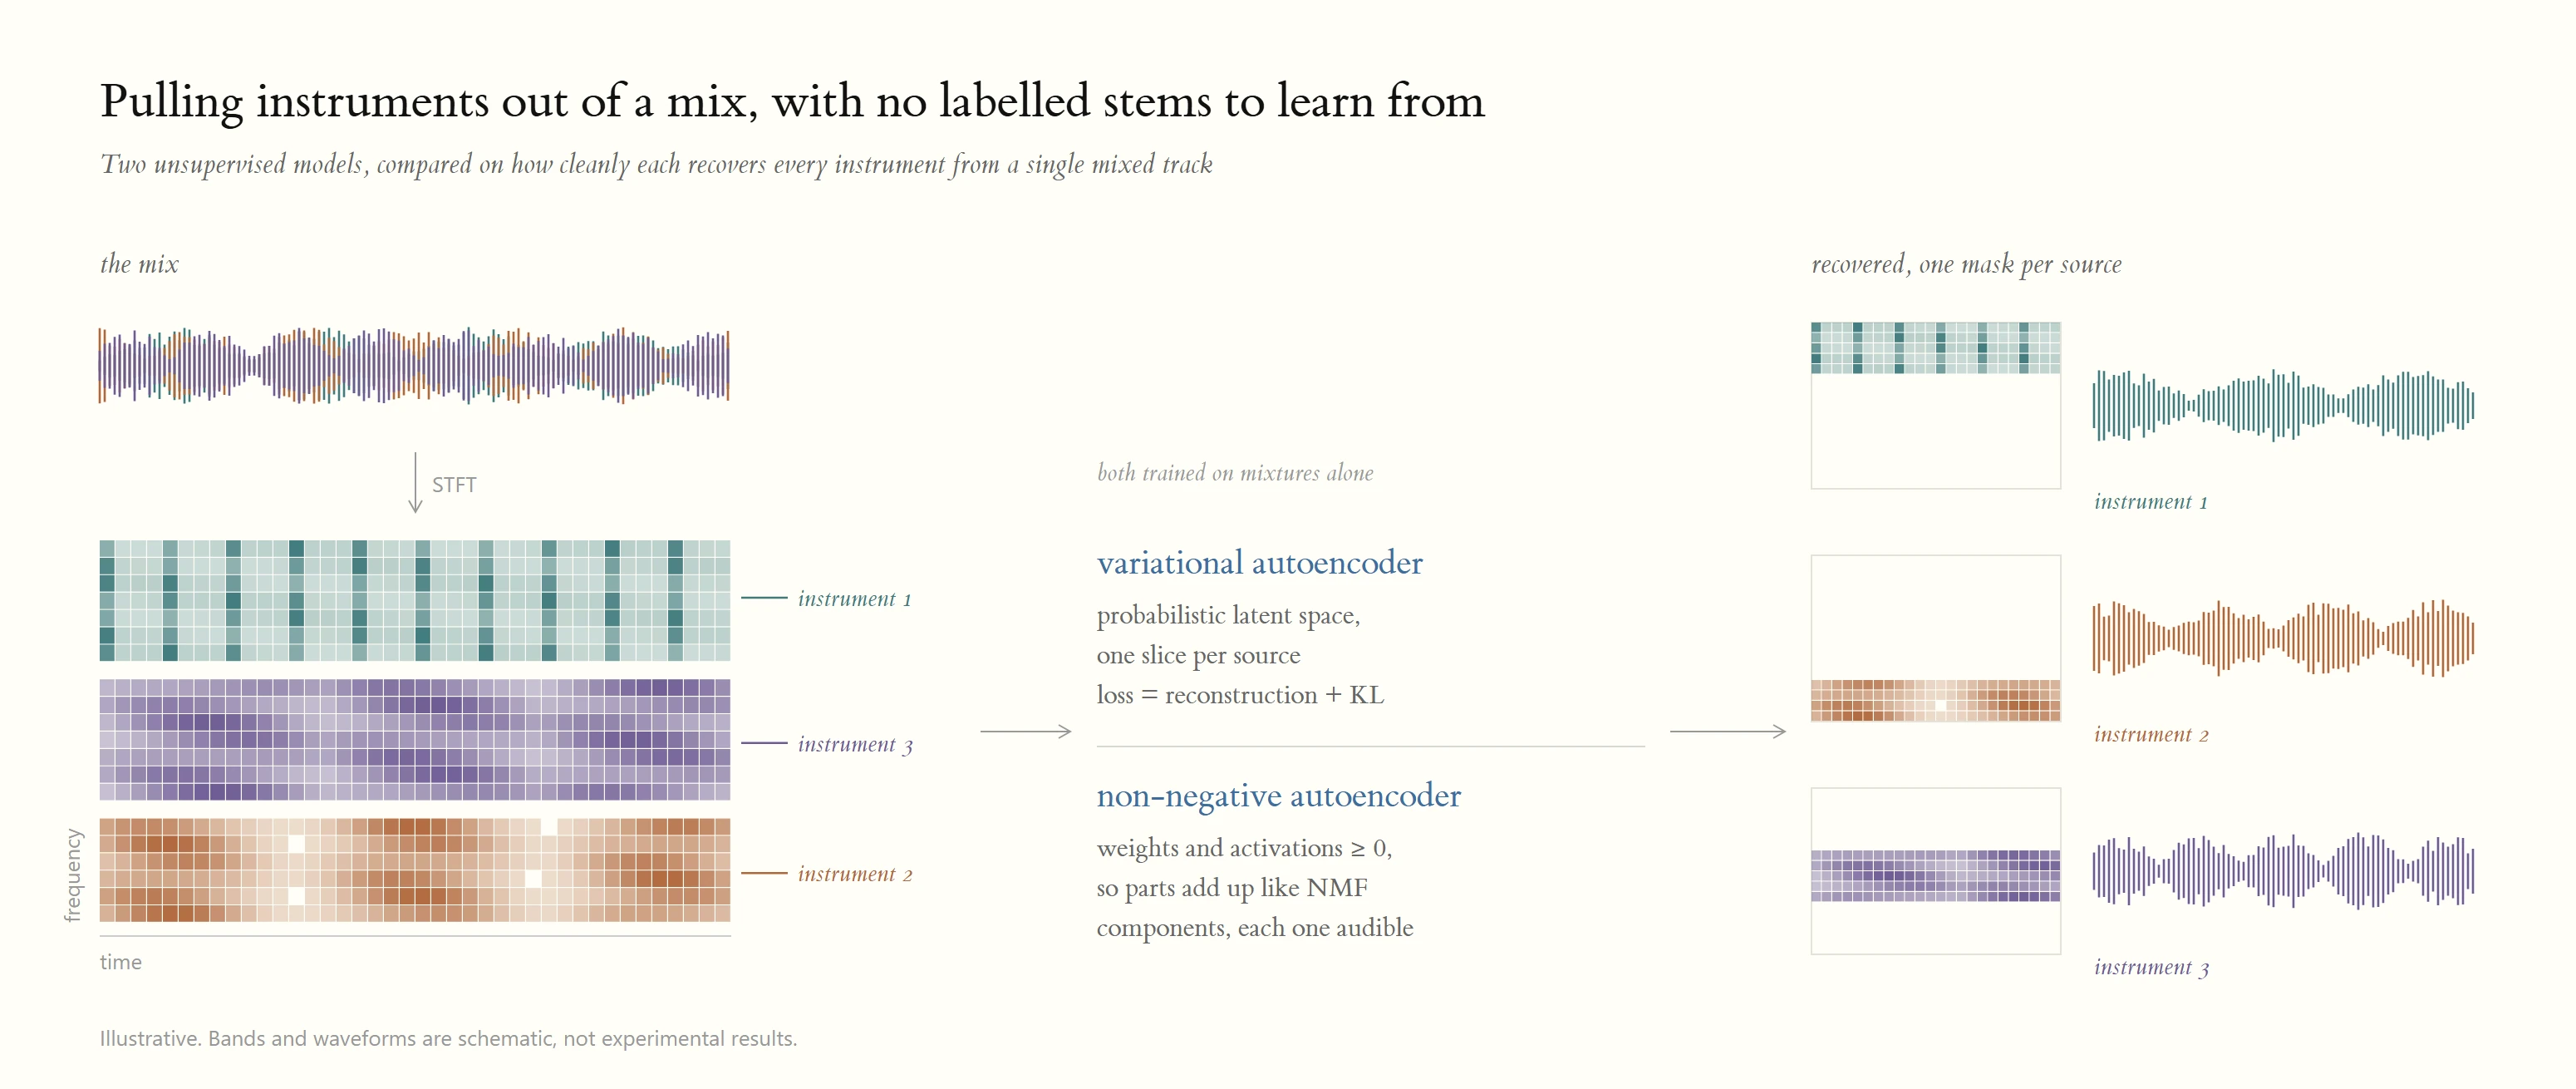
Source separation: a variational and a non-negative autoencoder, both trained on mixtures alone (illustrative)
CNMAT Labs
Teaching machines to hear sound in space
A semester of audio research at CNMAT, Berkeley's Center for New Music and Audio Technologies.
The first half was source separation: taking a mixed recording and pulling it apart into instrument stems without labelled training data. I worked with unsupervised variational autoencoders and non-negative autoencoders, comparing how cleanly each could recover individual instruments from a mix.
The second half was spatial sound. I built a Unity and C# environment on the Meta Quest where you place sound sources in a VR or AR scene you build yourself, and the audio is spatialized in real time as you move through it.